---
title: "5 Jev use cases for analytics, with real queries and datasets"
canonical: "https://motherduck.com/blog/jev-analytics-use-cases/"
related:
- title: "Jev for analytics: turn text columns into gold, in plain SQL | MotherDuck"
url: "https://motherduck.com/blog/jev-for-analytics/"
- title: "Jev (TypeSafe) | MotherDuck Docs"
url: "https://motherduck.com/docs/integrations/data-science-ai/typesafe/"
- title: "prompt_jev(): SQL-Native Text Classification | MotherDuck | MotherDuck"
url: "https://motherduck.com/videos/prompt-jev-sql-text-classification/"
gated_asset:
title: "AI Analytics Eval Field Guide"
url: "https://motherduck.com/lp/ai-analytics-eval-field-guide-full/"
---
# 5 Jev use cases for analytics, with real queries and datasets
Classifying text 30 times faster than gpt-5-nano, for about 1% of a frontier model's bill? It sounds crazy, but that's what we showed in the [first post about Jev for analytics](https://motherduck.com/blog/jev-for-analytics/): 100,000 complaints classified in 82 seconds.
Jev is a new type of decision model. It picks its answer from a closed list you define (yes or no, a label, a score) and returns a typed column with a confidence, fast enough to run on every row. On MotherDuck, you call it directly from SQL with the `prompt_jev()` function.
In this post, I'll go through 5 practical use cases on real datasets, with real results and shares you can attach to play around yourself.
## 1. AI agent logs: which turns worked, and which took the long way?
If you run an agent, your trace logs already say what happened: every model step, tool call, token and dollar. What they don't say is whether the turn did what the user asked, or whether it took the long way to get there. Making that kind of judgment call is where `prompt_jev()` shines.
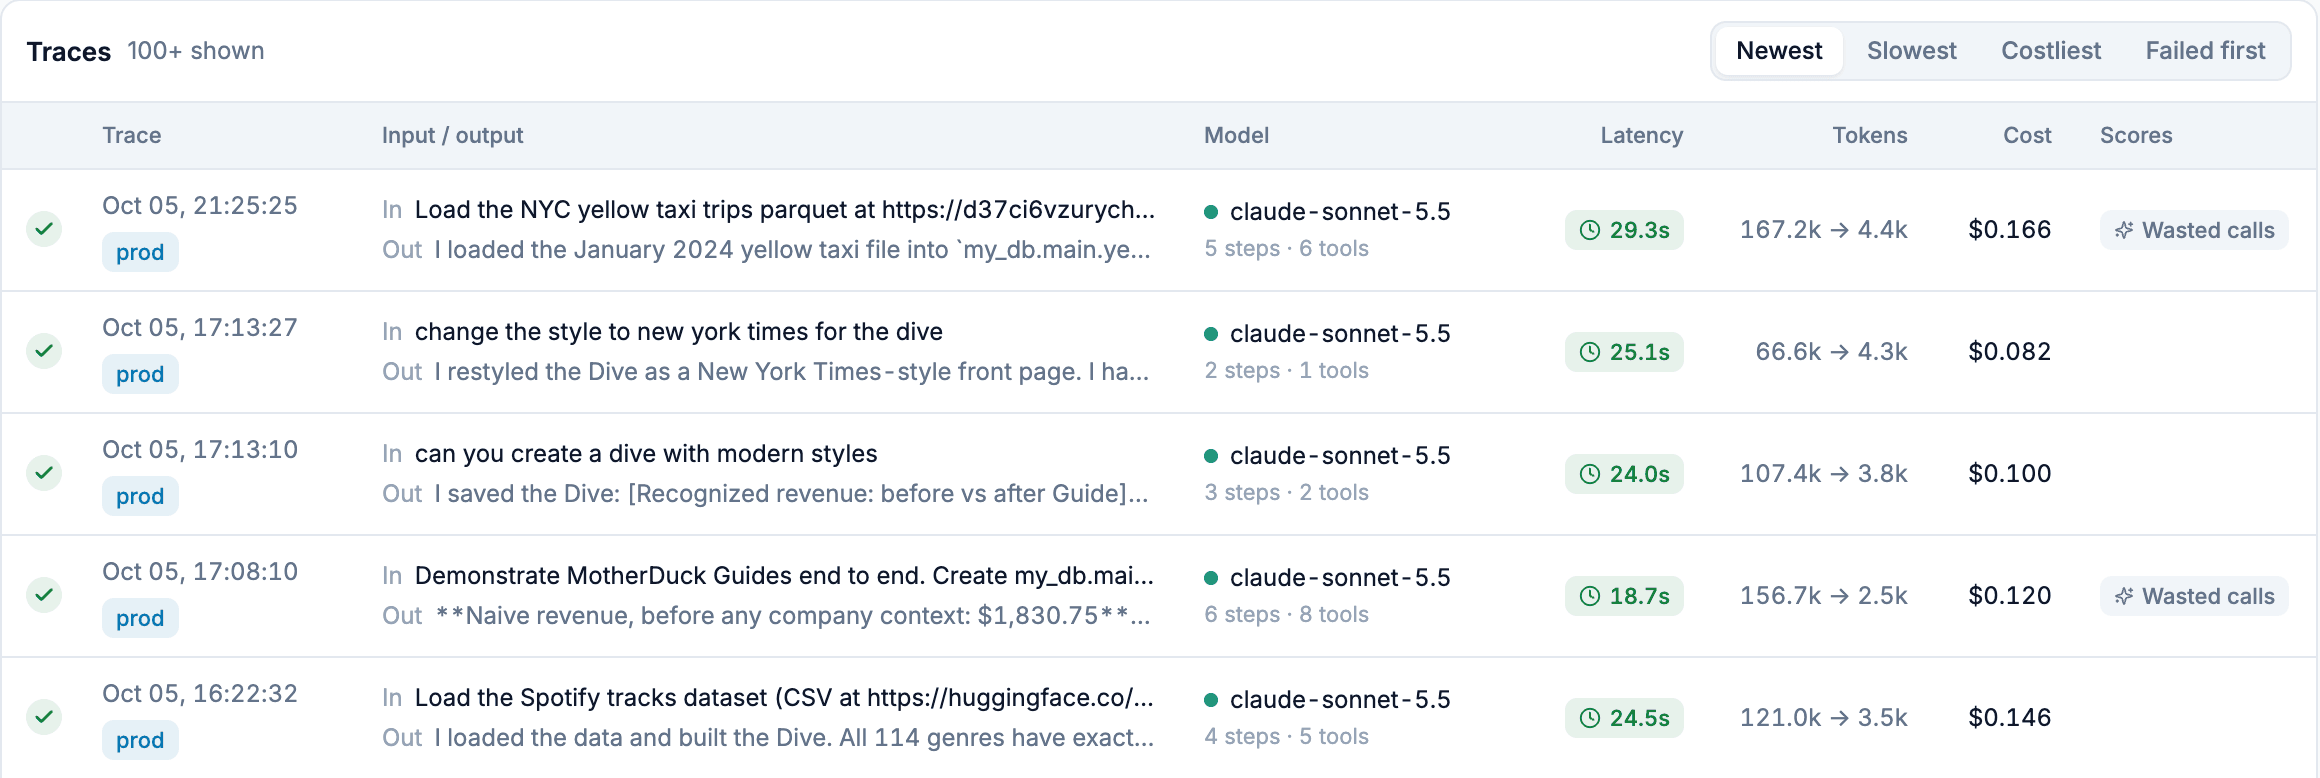
[motherduck.com/try](https://motherduck.com/try) lets anyone try MotherDuck by chatting with an agent that queries data, runs Flights and builds Dives through the MotherDuck MCP server. Every turn emits OpenTelemetry spans and writes them into a MotherDuck table.
Recent production turns in the /try observability Dive. The "Wasted calls" pill comes from prompt_jev().
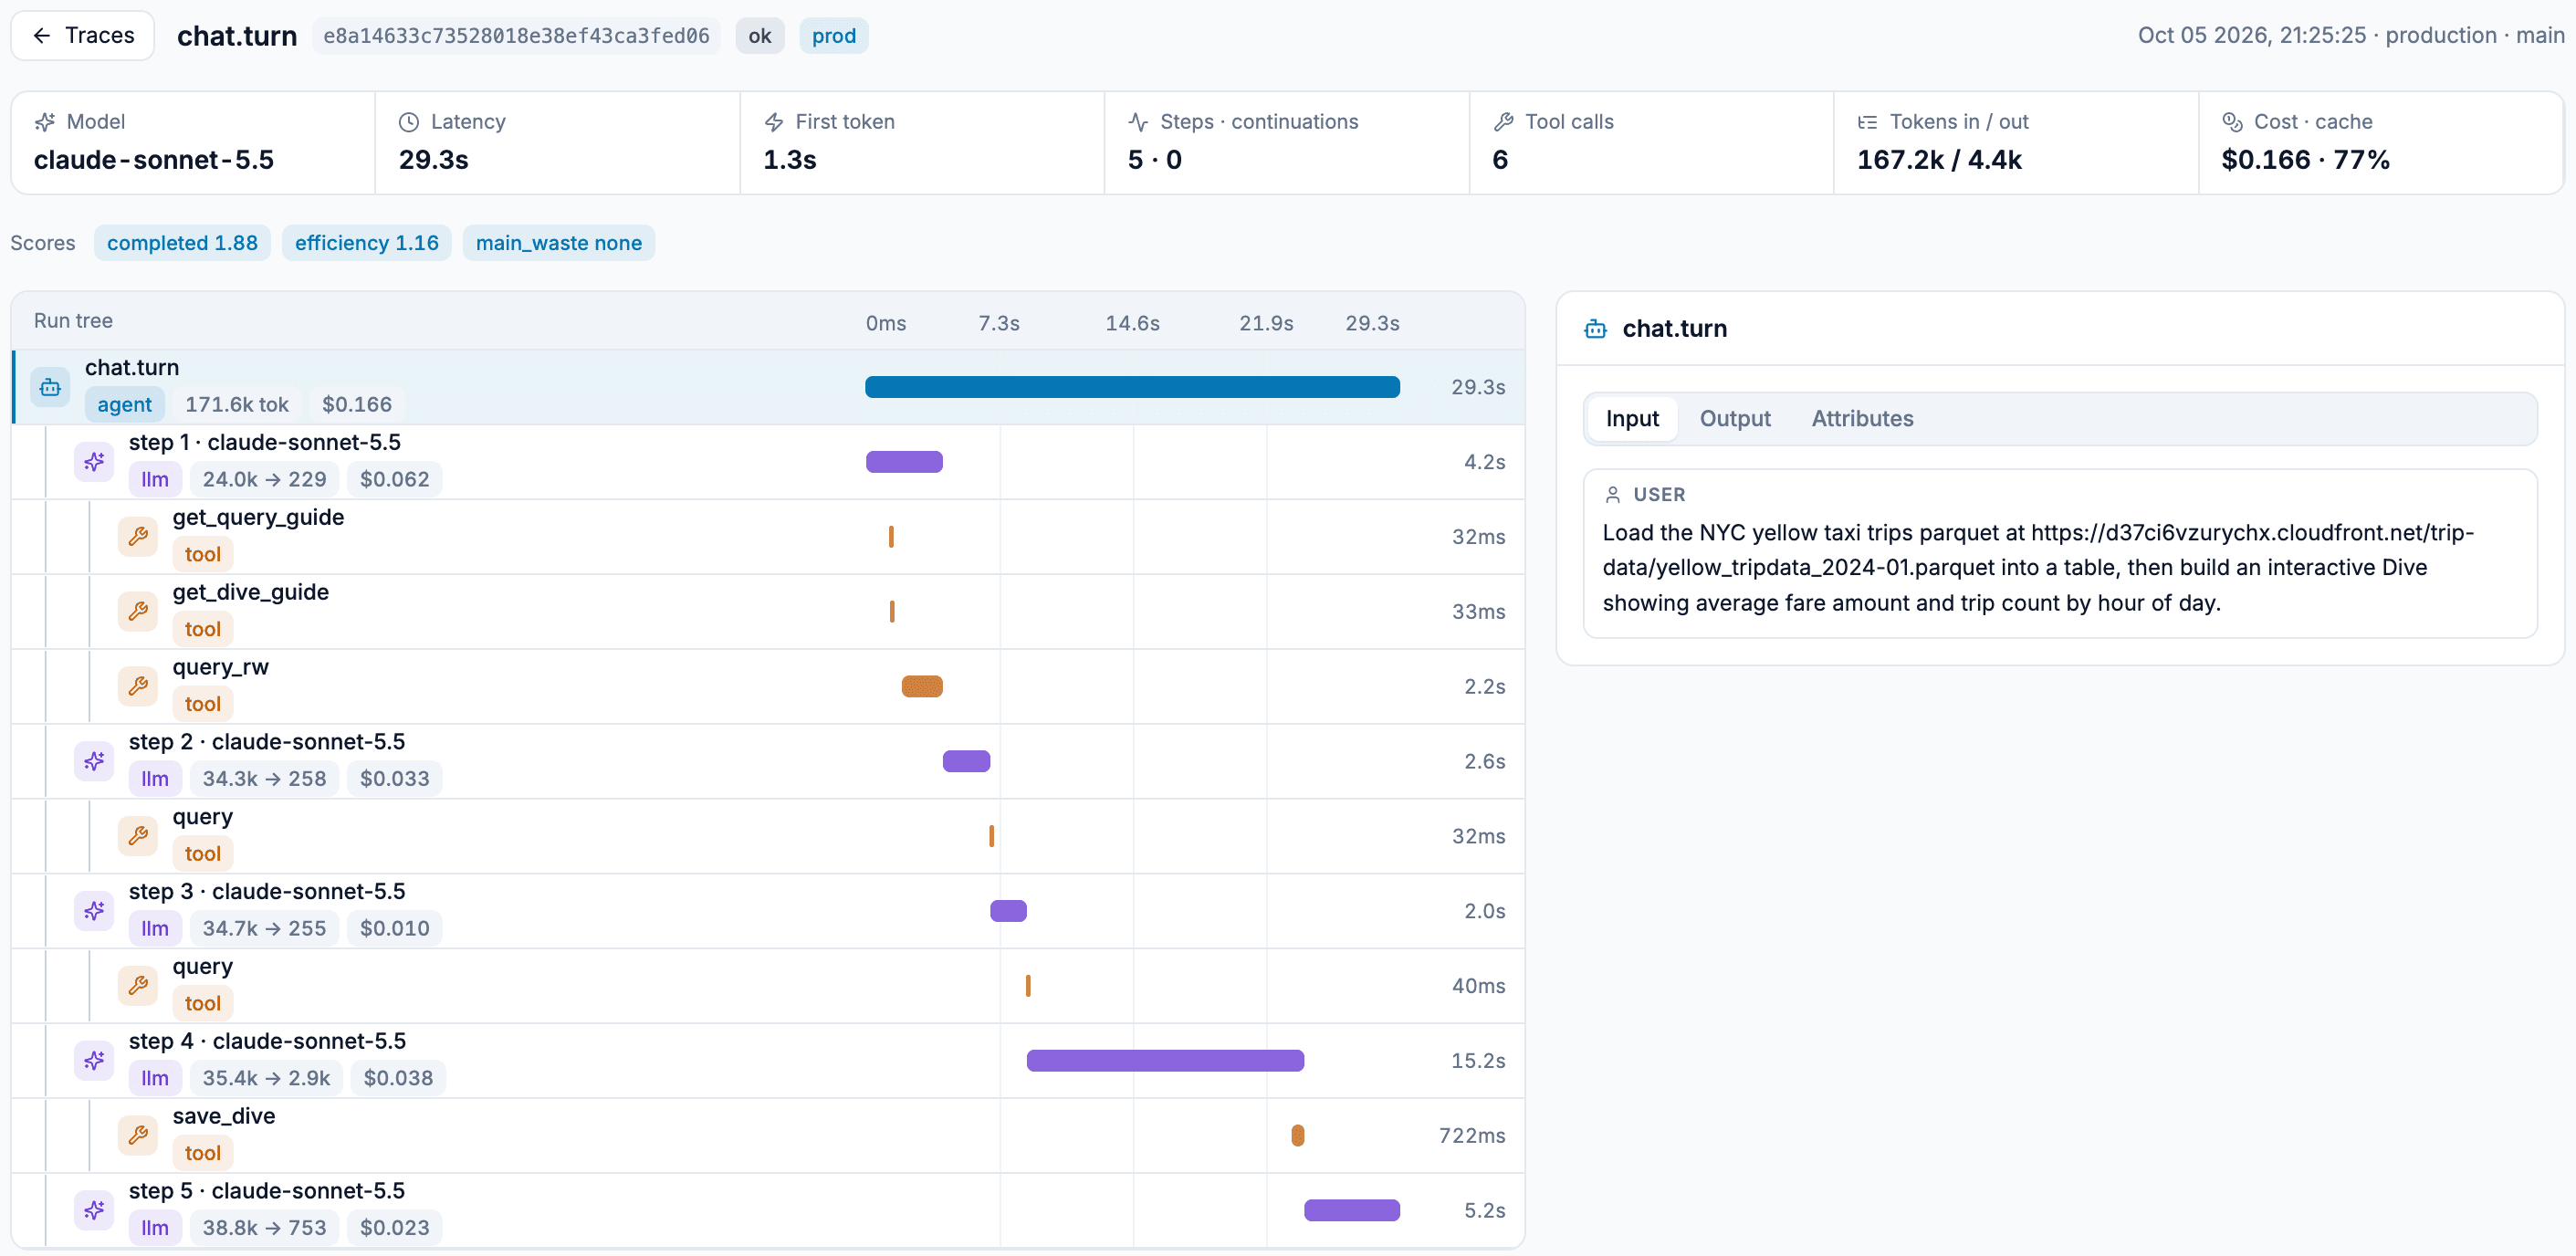
Open a turn and you get its full history, step by step, with the judge's scores on top:
This turn made 6 tool calls. efficiency says one or two were wasted, but main_waste says "none". When two questions disagree, the turn is worth a look.
We run a daily pipeline ([Flight](https://motherduck.com/docs/concepts/flights/)) which grades every production turn with a handful of questions, in SQL, next to the spans:
| question | asked on | Jev returns |
|---|---|---|
| `completed`: did the agent do what the visitor asked? | every turn | score: fails, partially, fully |
| `failure_mode`: why did it fall short? | turns that scored below 1.5 | choice: budget exhausted, tool or SQL error, wrong answer, ... |
| `error_cause`: what broke this tool call? | each failed tool call | choice: model wrote invalid SQL or Python, wrong guess about the data, platform error, tool bug |
| `efficiency`: how many tool calls were unnecessary? | turns with tool calls | score: many, a few, none wasted |
| `main_waste`: where did the waste come from? | turns that scored below 1.2 | choice: repeated failure, redundant read, polling, unneeded exploration, tool gap |
`efficiency` is the tricky one. Some calls look useless but are required by the product (reading a guide before using its tools, for example), so the instructions list them as never waste. Jev reads the request, the timeline of what the model wrote and called, and the start of the final answer:
```sql
prompt_jev(
'USER REQUEST: ' || left(request, 1500) || chr(10) ||
'TIMELINE (what the model wrote and the tool calls it made, in order):' || chr(10) || left(timeline, 8000) || chr(10) ||
'FINAL ANSWER (start): ' || left(coalesce(answer, ''), 1200),
questions := {
efficiency: {
type: 'score',
instructions: 'How many tool calls in the TIMELINE were unnecessary to answer the USER REQUEST?
These are required by the product and never waste:
- reading each guide once before first using its tools
- view_dive right after save_dive
- one wait_for_flight_run after each run_flight
A failed call followed by one corrected retry is not waste.',
criteria: ['many wasted (4 or more)', 'a few wasted (1 to 3)', 'none wasted']
}
}
)
```
Every example here uses MotherDuck and prompt_jev(), but the patterns apply to any stack with a similar setup: a System One model like Jev, which picks from answers you define.
Two interesting design choices:
- A cheap score on every turn, and the "why" questions only on the turns that score low. That keeps the cost down.
- Facts and judgments never mix: exact counts (repeated calls, extra waits) come from plain SQL on the spans. Jev only answers what needs judgment.
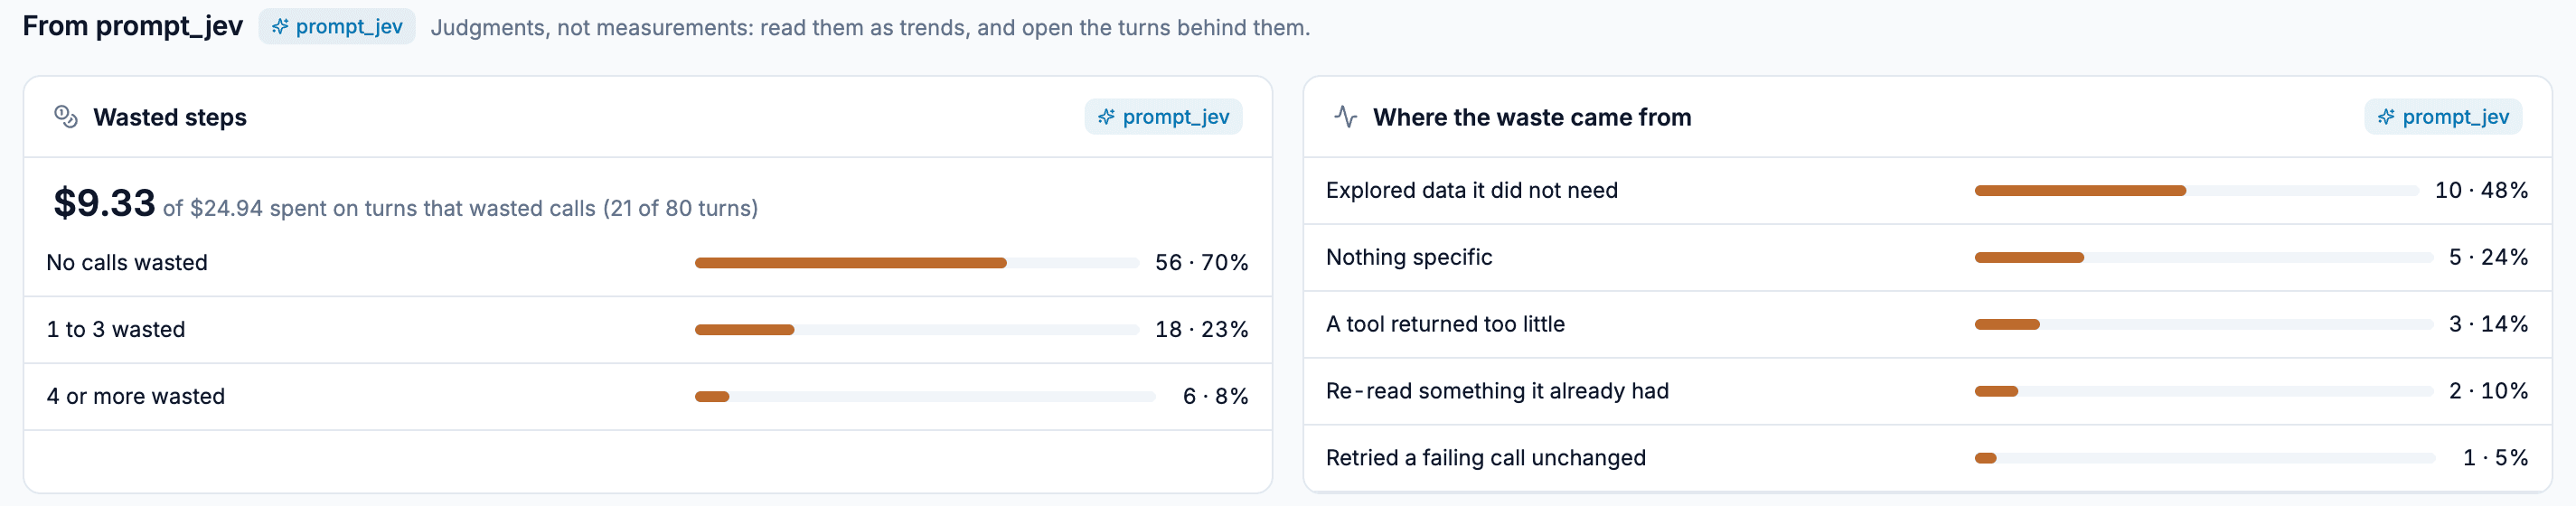
An example of the insights you get with prompt_jev(), which help you improve both your agent harness and the platform.
The same `prompt_jev()` judge grades our eval runs, where every case has an expected behavior. On the latest run, with 12 cases per model:
| model | cases passed | judge score | cost per turn |
|---|---:|---:|---:|
| Claude Opus 5.5 | 10 of 12 | 0.90 | $0.21 |
| GPT-6 Luna | 12 of 12 | 0.88 | $0.005 |
| Claude Sonnet 5.5 | 12 of 12 | 0.87 | $0.12 |
| GPT-5.6 Luna | 9 of 12 | 0.86 | $0.011 |
12 cases per model is still small, so treat this as a reason to run a bigger eval before switching models ;) But that's the decision table you want: quality next to cost, graded the same way every time, in the same database as the traces.
## 2. Social listening: what does Hacker News think of each AI lab?
Sentiment analysis is another big use case for text. It's hard to get right because people say the same thing in a hundred ways (hello, sarcasm). With Jev, you ask a simple question, "is this comment negative about X?", and get a clean classification back.
Tech adds its own problem: a lot of product names are ambiguous. "Claude" is also Claude Shannon, and "Gemini" is also a zodiac sign, an internet protocol, a NASA program and a crypto exchange. Good news: a prompt solves this one too.
Let's take Hacker News. MotherDuck hosts all of it in a share, refreshed daily: about 50M stories and comments since 2006. Attach it and you can rerun everything below:
```sql
ATTACH 'md:_share/hacker_news/daa0cc99-d20c-4f5c-abd5-f7b22a1a1da9' AS hacker_news;
```
I looked at four AI labs: OpenAI (ChatGPT and the GPT models), Anthropic (Claude), Google (Gemini, formerly Bard) and DeepSeek.
The first step is the one a regex would do: find every item that names one of them, with patterns like `\b(anthropic|claude)\b`. That's 488,483 mentions since 2019. Too many to classify for a blog post, so I took a stratified random sample: up to 1,000 mentions per lab per quarter, 65,635 in total, each weighted back to its quarter's full count. Every percentage below is weighted.
Then the prompt handles the name confusion. The date goes into the input, because Google's Gemini and Bard chatbots and Anthropic's Claude models didn't exist before 2023:
```sql
-- input = 'DATE: 2020-06' || chr(10) || 'NAMED PRODUCT: Google Gemini (formerly Bard)' || chr(10) || 'TEXT: ' || comment
SELECT id, lab,
prompt_jev(input,
'Does the TEXT use that name to mean the NAMED PRODUCT, the AI company or its AI models or chatbot (even if only in passing)? Use the DATE: Google''s Gemini and Bard chatbots and Anthropic''s Claude models did not exist before 2023. Answer no when the name means something else, such as the Gemini internet protocol, the NASA Gemini program or the zodiac sign, Claude Shannon or another person named Claude, the anthropic principle, a bard as in a poet, or GPT disk partitions.') AS refers
FROM mentions;
```
So how often was the regex wrong? Here's the share of regex matches that Jev says are about something else (`refers` below 0.5):
| lab | regex matches 2019-22 | about something else | regex matches 2023-26 | about something else |
|---|---:|---:|---:|---:|
| OpenAI | 22,623 | 2.0% | 261,266 | 1.1% |
| Anthropic | 795 | 89% | 144,131 | 0.8% |
| Google | 3,085 | 76% | 40,788 | 3.6% |
| DeepSeek | (didn't exist yet) | | 15,795 | 1.0% |
So before 2023, 89% of the HN items matching `claude` or `anthropic` weren't about the AI lab at all, mostly Claude Shannon and the anthropic principle. Once the Claude models shipped, that dropped to 0.8%. Gemini is the messiest one: still 3.6% wrong since 2023, because the Gemini protocol, the NASA program and the crypto exchange keep showing up. Yes, that's a lot of Geminis out there.
The cool thing is that we can ask **4 questions in one call per comment**: the name check above, whether the comment is really about the lab, whether it's negative, and what it's about. The instructions of `prompt_jev()` must be constants, so the lab goes into the input:
```sql
SELECT id, lab,
prompt_jev(input, questions := {
refers: {type: 'noul', instructions: '...the name check above...'},
relevant: {type: 'noul', instructions: 'Is the TEXT about the NAMED PRODUCT itself (the AI company, its models or its assistant), rather than only mentioning it in passing?'},
negative: {type: 'noul', instructions: 'Does the author express a negative experience with, or a negative opinion of, the NAMED PRODUCT?'},
topic: {type: 'choice', instructions: 'What aspect of the NAMED PRODUCT is the TEXT mainly about?',
criteria: ['answer quality and hallucinations', 'coding and developer tools', 'pricing and usage limits', ..., 'not about the product']}
}) AS r
FROM mentions;
```
Each comment goes through the four questions, and the answers decide where it ends up:
| comment (trimmed) | lab | r.refers | r.relevant | r.negative | r.topic.choice | counted as |
|---|---|---:|---:|---:|---|---|
| "Crypto exchange Gemini reveals lower revenue and wider loss in US IPO filing" | Google | 0.06 | 0.11 | 0.14 | not about the product | dropped: wrong Gemini |
| "Earthquake Scatter Plot Santorini (done with some help from ChatGPT)" | OpenAI | 0.94 | 0.11 | 0.07 | coding and developer tools | dropped: only in passing |
| "Tested out Gemini-2 Flash [...] It still hallucinates like crazy compared to GPT-4o." | Google | 0.97 | 0.97 | 0.97 | answer quality and hallucinations | negative |
| "A nice thing about Deepseek is that it is so cheap to run." | DeepSeek | 0.94 | 0.91 | 0.04 | pricing and usage limits | not negative |
Jev gives us a confidence score, so we can filter on it to make the output more reliable. For instance, "clearly negative" means `r.negative >= 0.8`, counted only on comments that are really about the lab (`refers >= 0.5`, `relevant >= 0.8`, and a topic other than "not about the product").
The usual caveats apply. Hacker News is a loud, developer-heavy crowd where coding tools loom large, so use your human judgment: don't read this as market share :)
Here's the full dive, also available on the [dive gallery](https://motherduck.com/dive-gallery/dives/what-does-hacker-news-think-of-each-ai-lab).
The sample and the Jev labels are in a public share if you want to run your own queries:
```sql
ATTACH 'md:_share/hn_ai_labs_public/3b78bda2-5bf1-4e0f-9e4b-f4ecb168405b' AS hn_ai_labs;
```
## 3. Sales calls: which conversations match the use cases we serve?
It's never been easier to record a meeting and get the transcript: tons of tools do it natively. At MotherDuck, I use it to understand what our customers ask for and which walls they hit in their developer experience and onboarding.
For the demo here, though, I'll take a made-up sales case.
Typically, the CRM knows the account size and the contact's title. The call transcript knows what they're trying to do. Joining the two is where lead scoring gets interesting (and that is how sales decides which leads to call first).
Say `sales_calls` has `call_id`, `account_id` and `transcript`, and `accounts` holds your firmographic enrichment. Ask a narrow yes/no question about a documented product fit, for example whether the prospect needs to analyze lots of customer conversations or reviews. Then use the answer as one signal in a review queue:
```sql
-- Illustrative schema and product-fit question.
WITH calls AS (
SELECT call_id, account_id,
prompt_jev(transcript,
'Does the prospect describe a need to analyze many customer conversations or reviews?')
AS text_analytics_fit
FROM sales_calls
)
SELECT c.call_id, a.segment, a.contact_role, c.text_analytics_fit
FROM calls c
JOIN accounts a USING (account_id)
WHERE c.text_analytics_fit >= 0.8;
```
A sample of the shortlist (illustrative):
| call_id | segment | contact_role | transcript snippet | text_analytics_fit |
|---|---|---|---|---:|
| 4812 | mid-market | Head of Data | "we have 2M support chats a year and nobody reads them" | 0.94 |
| 4830 | enterprise | Analytics Engineer | "our NPS comments sit in a varchar column in Snowflake" | 0.88 |
Again, treat the output as a shortlist for a human to check. A high score doesn't make anyone a "good lead". If title or seniority matters, use the CRM field you already have instead of asking a model to guess it from the transcript. And if your product covers several use cases, ask one well-defined question per use case and validate the thresholds on labelled calls.
## 4. Job postings: which cloud does each market actually run on?
Which cloud provider is the best?
OK, wrong question. What I actually want to know is which cloud provider wins, and where.
Job postings are a decent proxy: a company hiring Azure data engineers is betting on Azure for the next few years. Five years ago, I wrote a [blog](https://medium.com/datadriveninvestor/what-are-the-most-requested-technical-skills-in-the-data-job-market-insights-from-35k-datajobs-ads-d8642555f89e) about the most requested skills in 35k data job postings I scraped. Parsing them was hard work: I had to train a small model just to classify a few things in each posting.
The catch is that titles don't say which cloud, and keyword counts lie. Plenty of postings list "AWS, Azure or GCP" as a nice-to-have, and "AWS is a plus" doesn't mean the stack runs on AWS. So instead of counting keywords, I asked Jev one question per posting.
The data is 650k data job postings that mention at least one cloud. Most are Google Jobs postings for 21 European countries and the US, from [Luke Barousse's Data Nerds](https://datanerd.tech) dataset, plus 2025 LinkedIn postings for eight cities from my colleague Dumky's [`data_jobs_2025` sample dataset](https://motherduck.com/docs/getting-started/sample-data-queries/job-postings/). To keep tokens low, I didn't send the full description: the input is the job title plus only the sentences that name a cloud, about 750 characters instead of 4,200.
```sql
SELECT source, job_id, country_code,
prompt_jev(snippet,
'Which cloud platform is this data job''s stack primarily built on?',
choice := ['aws', 'azure', 'gcp', 'ovhcloud', 'scaleway', 'ionos', 'stackit',
'hetzner', 'open telekom cloud', 'oracle cloud', 'ibm cloud',
'alibaba cloud', 'multi-cloud, no clear primary',
'cloud only mentioned in passing']) AS r
FROM jev_candidates;
```
Watch the last two labels. They're the escape hatches: without them, Jev is forced to pick a cloud even when the posting doesn't really have one.
| title | excerpt sent to Jev | r.choice | confidence |
|---|---|---|---:|
| Data Engineer (DE) | "Du verwaltest und optimierst Datenpipelines in MS Azure Data Factory ... Datenmodelle ... in Synapse Analytics" | azure | 1.00 |
| AI Data Engineer (DE) | "General knowledge of AWS cloud services like AWS Batch, ECS Fargate, S3, RDS" | aws | 1.00 |
| Alternance - Data Engineer (FR) | "Google Cloud (BigQuery, Cloud Storage, ...)" | gcp | 1.00 |
| Sr Data Engineer (US) | "Leverage cloud platforms like AWS, GCP, or Azure to build and manage data solutions" | multi-cloud, no clear primary | 0.95 |
| Senior Data Engineer (US) | "AWS cloud experience is a plus" | cloud only mentioned in passing | 0.50 |
| Data Scientist (US) | "Cloud Certification (AWS/Azure preferred)" | multi-cloud, no clear primary | 0.57 |
Also cool: I didn't translate anything first. The question is in English, and the postings are in German, French, Italian and more (welcome to Europe!).
For the map, I only count a posting when all of these are true:
- it wasn't posted by a cloud vendor (AWS hiring for AWS says nothing about the market)
- it names a single cloud
- Jev picked a real cloud, not an escape hatch, with a confidence of at least 0.8
```sql
SELECT country_code, r.choice AS cloud, count(*) AS postings
FROM classified
WHERE posted_by_provider IS NULL -- drop postings by the cloud vendors
AND n_clouds_mentioned = 1 -- one cloud named in the posting
AND r.confidence >= 0.8
AND r.choice NOT IN ('multi-cloud, no clear primary', 'cloud only mentioned in passing')
GROUP BY ALL;
```
Of 396k postings from 2024-25, 213k survive these filters. And the answer: Europe runs on Azure, which leads in 18 of 21 countries. The US is split: Azure leads more states (25 against 22 for AWS), but the AWS states carry three times more postings.
Play with it yourself: switch between Europe and the US, focus on a single cloud, and hover any country or state for the full split.
The full Dive is also on the [dive gallery](https://motherduck.com/dive-gallery/dives/cloud-is-regional-which-cloud-do-data-job-ads-ask-for). The aggregates behind the map are public too:
```sql
ATTACH 'md:_share/cloud_regionality_public/10d8fd77-a5f7-42e5-95d5-6cd999bf8535' AS cloud_regionality;
```
## 5. Skip the hand-written parser: is this job remote?
This one is more technical, but it pays off in maintenance and speed. To turn a text column into a category, you write a parser. Usually that's a `CASE WHEN` (or worse, a custom UDF) with a few regexes that someone wrote once and keeps patching.
So let's take a sample of the job postings above and ask: is the job remote, hybrid, on-site, or doesn't the posting say?
You can follow along by attaching this database:
```sql
ATTACH 'md:_share/jev_use_cases/6a306d41-76e6-4cca-828b-84f412a28009' AS jev_use_cases;
```
The classic regex version typically looks like this:
```sql
CASE
WHEN description ILIKE '%hybrid%' THEN 'hybrid'
WHEN description ILIKE '%remote%' THEN 'remote'
WHEN regexp_matches(description, '(?i)\bon-?site\b|\bin[- ]office\b') THEN 'on-site'
ELSE 'not stated'
END
```
Then you hit the obvious false positives, like "remote sensing" or "hybrid cloud". You keep patching and end up with something that kind of works, but is hard to maintain (my version two has 22 hand-tuned alternatives and exclusion lists).
The Jev version is one question, with the definitions written down:
```sql
SELECT job_id,
prompt_jev('TITLE: ' || title || chr(10) || 'LOCATION: ' || location || chr(10) ||
'DESCRIPTION: ' || left(description, 8000),
'Where does this job expect the person to work?',
choice := [
{label: 'remote', description: 'Fully remote: work from home or anywhere all the time, possibly limited to a country or time zone'},
{label: 'hybrid', description: 'A mix of home and office: some days a week in the office, or remote work, home office or télétravail offered as a regular option or benefit'},
{label: 'on-site', description: 'The posting says the work is at the office, a site or a client site, with no regular remote work'},
{label: 'not stated', description: 'The posting does not say whether the work is remote, hybrid or in the office'}
]) AS work_mode
FROM jev_use_cases.job_postings_sample;
```
How does it compare with the regex and a standard LLM call (`prompt()`)? On the same 2,000 postings:
| approach | time on 2,000 postings | what you have to maintain |
|---|---:|---|
| regex, version two | 0.2 s | 22 hand-tuned alternatives and exclusion lists |
| `prompt()` with an ENUM return type | 37.0 s | the prompt |
| `prompt_jev()` | 1.7 s | the label definitions |
`prompt_jev()` is again about 20 times faster than the LLM call, and asking the LLM for JSON didn't help much (31.1 s, before the cleanup). The regex is still the fastest, but Jev is fast enough to replace it without the fragility, and it skips the slow LLM detour.
So should you use Jev everywhere you have text?
Well, a regex is still nice for structure: things that have a format (IDs, emails, URLs, dates, a known product code). Use Jev for meaning: is this about X, is it negative, which one is the main one. And use both together: a cheap `ILIKE` or regex to build the shortlist, then `prompt_jev()` to decide.
## A good first experiment
Pick a text column you already have and a business question you couldn't answer from it (or only the hard way). Write down the answers you'd accept. Label a small sample by hand (or with `prompt()` on MotherDuck or with a standard LLM call), run `prompt_jev()` on it, and look at both the winners and the uncertain rows. Once the question holds up, materialize the result so your dashboard doesn't pay to classify the same text twice.
Keep the limits in mind: Jev gives you a bounded choice, a yes/no probability or an ordered score. It won't write a summary or invent a new category. Test your confidence threshold on your own data, and check your data-handling rules before sending customer text to an AI function. The [MotherDuck guide](https://motherduck.com/docs/key-tasks/ai-and-motherduck/classify-text-with-prompt-jev/) and the [`prompt_jev()` reference](https://motherduck.com/docs/sql-reference/motherduck-sql-reference/ai-functions/prompt-jev/) cover the syntax and availability.
For now, the duck-sized test is simple: what question is hiding in a text column you already own?