Pricing model
MotherDuck pricing model
MotherDuck is a serverless cloud data warehouse built on DuckDB. We believe in providing our users with simple pricing.
MotherDuck offers two self-serve plans: Lite and Business.
MotherDuck is available on AWS in six regions across the US, Europe, and Asia Pacific. Each MotherDuck Organization is scoped to a single cloud region that must be chosen at Org creation when signing up. Compute and storage rates vary by region and are grouped into three pricing tiers. See Cloud regions for the full list.
Plan comparison
| Feature | Lite | Business | Enterprise |
|---|---|---|---|
| Best for | Individual users, small projects | Teams and organizations | Bespoke deployments: Contact us |
| Platform fee | $0/month | $250/month | Custom |
| Compute included | Includes 10 Compute Unit (CU) hours / month + Pay-as-you-go for additional usage | Pay-as-you-go for additional usage | Custom |
| Duckling sizes | Pulse only | Pulse, Standard, Jumbo, Mega, Giga | Pulse, Standard, Jumbo, Mega, Giga |
| Read Scaling | - | Yes | Yes |
| Flight sizes | F4 (with limits); F4, F16 (unlimited) | F4, F16, F32 | F4, F16, F32 |
| Flights | 30 min compute / day, on-demand runs (no credit card required); monthly compute allocation + usage-based pricing with a credit card, plus scheduling and unlimited concurrent runs (1-hour maximum per run) | Usage-based pricing includes scheduling and unlimited concurrent runs (8-hour maximum per run) | Custom |
| Storage included | Includes 10 GB / month + Pay-as-you-go for additional usage | Pay-as-you-go for additional usage | Custom |
| Users | 3 active users / 2 service accounts | 10 active users / unlimited service accounts | Custom |
| SLA | - | 99.9% Availability | 99.9% Availability |
| Backup | 1 day (paid feature) | - Point-in-time Restore - up to 90 day backups | Custom |
| Observability | - | Query history | Query history |
Users are defined as human users with a login through email + password, Google, GitHub, or SSO, while Service Accounts are defined as non-human accounts designed for programmatic access and automation workflows (for example, backend services, integrations, or customer-facing analytics).
Flights are available on all plans. Compute limits, scheduling, and per-run caps vary by plan. Lite plan users can access scheduling and unlimited concurrent runs by adding a credit card. See Flights for details.
Compute pricing
A Duckling in MotherDuck is a compute instance. There are 5 Duckling sizes available on the Business plan: Pulse, Standard, Jumbo, Mega, and Giga.
MotherDuck meters compute per-second. While Standard, Jumbo, Mega, and Giga Ducklings are billed for wall clock time, Pulse Ducklings are metered on a per-query basis to support variable, ad-hoc queries. As a result, they are on-demand and auto-scaling.
Non-Pulse Ducklings have a cooldown period, which is the amount of time the Duckling will remain active after completing the last query. This keeps the Duckling warm for follow-up queries that may benefit from MotherDuck's intelligent storage and caching.
The cooldown period is configurable for Standard, Jumbo, Mega, and Giga Ducklings, with a 1-minute minimum.
Pulse Ducklings are metered on a per-query basis, with a minimum of 1 Compute Unit (CU) second instead of wall-clock time: They do not have a configurable cooldown. A Compute Unit (CU) is defined as the amount of CPU and memory usage over time.
If you want to group query history by integration, pipeline, or tenant, set custom_user_agent when connecting to MotherDuck and query MD_INFORMATION_SCHEMA.QUERY_HISTORY. See Tag workloads with custom user agents for an example pattern. Some teams use that breakdown in internal allocation, but MotherDuck billing still follows the pricing model on this page.
The SHUTDOWN and SHUTDOWN TERMINATE commands can be used to shut down a Duckling without waiting for the cooldown period. SHUTDOWN waits for running queries to complete, and SHUTDOWN TERMINATE force-terminates immediately.
Duckling sizes
| Duckling | Billing | Default Cooldown | Configurable Cooldown Period | Details |
|---|---|---|---|---|
| Pulse | Per Compute Unit (CU) (resources consumed), not wall-clock time | N/A | N/A | Small, variable queries, read-heavy workloads, and frontend scenarios. For compute-heavy queries, consider Standard instead. Billing example: 2 queries x 10s = 20 CU seconds. |
| Standard | Per second | 1 minute | 1 min to 24 hours | General purpose data warehouse workloads. Billing example: 5 queries × 30s + 100ms startup + 60s cooldown = 210 seconds. |
| Jumbo | Per second | 1 minute | 1 min to 24 hours | Large-scale data warehouse workloads. Billing example: 2 queries × 8min + 100ms startup + 60s cooldown = 17 minutes. |
| Mega | Per second | 5 minutes | 1 min to 24 hours | Demanding jobs and large-scale workloads. Billing example: 2 queries × 8min + few min startup + 5min cooldown = ~21 minutes. |
| Giga | Per second | 10 minutes | 1 min to 24 hours | Batch jobs and overnight or weekend processing. Billing example: 2 queries × 5min + few min startup + 10min cooldown = ~20 minutes. |
Changing your Duckling size to Pulse, Standard, or Jumbo through the UI or REST API may take up to 2 minutes. Switching to a Mega takes up to 5 minutes, while switching to a Giga takes up to 10 minutes.
Compute
Compute pricing depends on the cloud region your Organization runs in. Regions are grouped into three pricing tiers:
| Tier | AWS Regions |
|---|---|
| Tier 1 | US East (N. Virginia) us-east-1, US West (Oregon) us-west-2 |
| Tier 2 | Europe (Frankfurt) eu-central-1, Europe (Dublin) eu-west-1 |
| Tier 3 | Asia Pacific (Tokyo) ap-northeast-1, Asia Pacific (Sydney) ap-southeast-2 |
Business Plan
| Tier | AWS Regions | Pulse | Standard | Jumbo | Mega | Giga |
|---|---|---|---|---|---|---|
| Tier 1 | US East (N. Virginia) us-east-1, US West (Oregon) us-west-2 | $0.60 per hour | $2.40 per hour | $4.80 per hour | $12.00 per hour | $24.00 per hour |
| Tier 2 | Europe (Frankfurt) eu-central-1, Europe (Dublin) eu-west-1 | $0.73 per hour | $2.93 per hour | $5.86 per hour | $14.65 per hour | $29.30 per hour |
| Tier 3 | Asia Pacific (Tokyo) ap-northeast-1, Asia Pacific (Sydney) ap-southeast-2 | $0.77 per hour | $3.10 per hour | $6.19 per hour | $15.48 per hour | $30.96 per hour |
Lite Plan
| Tier | AWS Regions | Pulse |
|---|---|---|
| Tier 1 | US East (N. Virginia) us-east-1, US West (Oregon) us-west-2 | $0.60 per hour |
| Tier 2 | Europe (Frankfurt) eu-central-1, Europe (Dublin) eu-west-1 | $0.73 per hour |
| Tier 3 | Asia Pacific (Tokyo) ap-northeast-1, Asia Pacific (Sydney) ap-southeast-2 | $0.77 per hour |
The Lite plan includes 10 CU hours on Pulse per month. Additional usage is billed at the rates above.
Flights pricing
Flights are billed for the time each run takes, at the hourly rate for the Flight's size. There are 3 Flight sizes: F4, F16, and F32. See Flight sizes for the plans each size is available on and what each size is good for.
Flight pricing depends on the pricing tier of your Organization's cloud region.
| Tier | AWS Regions | F4 | F16 | F32 |
|---|---|---|---|---|
| Tier 1 | US East (N. Virginia) us-east-1, US West (Oregon) us-west-2 | $0.15 per hour | $0.60 per hour | $1.20 per hour |
| Tier 2 | Europe (Frankfurt) eu-central-1, Europe (Dublin) eu-west-1 | $0.18 per hour | $0.73 per hour | $1.46 per hour |
| Tier 3 | Asia Pacific (Tokyo) ap-northeast-1, Asia Pacific (Sydney) ap-southeast-2 | $0.19 per hour | $0.77 per hour | $1.55 per hour |
On Lite (unlimited), Flight usage draws from the same monthly compute allocation as Ducklings. Usage beyond the allocation is billed at the rates above. Lite (with limits) includes 30 minutes of Flight compute per day at no charge.
Storage pricing
Under the hood, MotherDuck uses DuckDB's compression algorithms to reduce the storage footprint and optimize performance. MotherDuck charges for data stored in its managed storage system based on your average storage usage over the billing period. Your monthly bill is calculated as the average of your daily storage (in GB) multiplied by the per-GB rate.
For example, if your MotherDuck Organization is in us-east-1 and your average storage over December is 650 GB, the final bill will be computed as follows:
- 650 GB × $0.04/GB = $26.00
What counts towards my storage bill?
- Standard databases: MotherDuck provides point-in-time restore by retaining historical data as
historical_bytesfor organizations on paid plans. - Transient databases: Databases can be set as
TRANSIENTat database creation. Transient databases are billed for active data stored and a 1-day failsafe minimum. Data is not retained as failsafe bytes beyond this minimum, which is ideal for temporary or reproducible datasets like intermediate job outputs. - NOTE: By default, for both Standard and Transient databases, new databases retain 1 day of historical data on Lite (paid) and 7 days of historical data on Business - Business plan users are able to configure their
historical_bytesretention window from 0 to 90 days. Users are billed for active data plus historical, retained, and failsafe bytes. Refer to the Storage Lifecycle for more details.
What does not count towards my storage bill?
- Shares do not incur additional data storage as they are a zero-copy operation.
- Using the CREATE DATABASE X FROM DATABASE Y command is also a zero-copy operation. Only incremental changes made to the new database are added to storage as
active_bytes, while active Shares that point to a deleted databases will retainretained_for_clone_bytes. - Any data managed by you in your own object storage bucket, for example S3, Blob, or GCS, that you can use to process data.
- Data on your laptop accessed through the
duckdb -ui, even when signed into MotherDuck.
What changes can I make to optimize my storage bill?
The right approach to optimize storage usage in MotherDuck varies by use case and implementation. Please reach out to us at support@motherduck.com for additional guidance on how to optimize your storage effectively for your needs.
Storage rates
Storage pricing depends on the cloud region your Organization runs in, using the same tiers as compute:
| Tier | AWS Regions | Cost per GB/month |
|---|---|---|
| Tier 1 | US East (N. Virginia) us-east-1, US West (Oregon) us-west-2 | $0.04 / GB |
| Tier 2 | Europe (Frankfurt) eu-central-1, Europe (Dublin) eu-west-1 | $0.043 / GB |
| Tier 3 | Asia Pacific (Tokyo) ap-northeast-1, Asia Pacific (Sydney) ap-southeast-2 | $0.044 / GB |
Storage is billed based on your average usage over the billing period.
Lite plan includes 10 GB of free storage. Additional storage is billed at the rates above.
AI function pricing
AI functions are billed in AI Units, where 1 AI Unit = $1.00. Usage can consume a fraction of an AI Unit. The billing unit stays the same across models, but the amount of work it buys depends on the function and model.
- FixIt is free.
- SQL Assistant functions are billed per call.
promptis billed on input and output tokens at model-specific rates.embeddingandprompt_jevare billed on input tokens only.
AI charges are separate from the compute and storage charges for your queries and data.
Advanced AI functions
Advanced AI functions generate text, create embeddings, or classify data. They are billed on model token usage, rather than a fixed charge per row. Longer inputs, longer responses, and additional calls increase consumption.
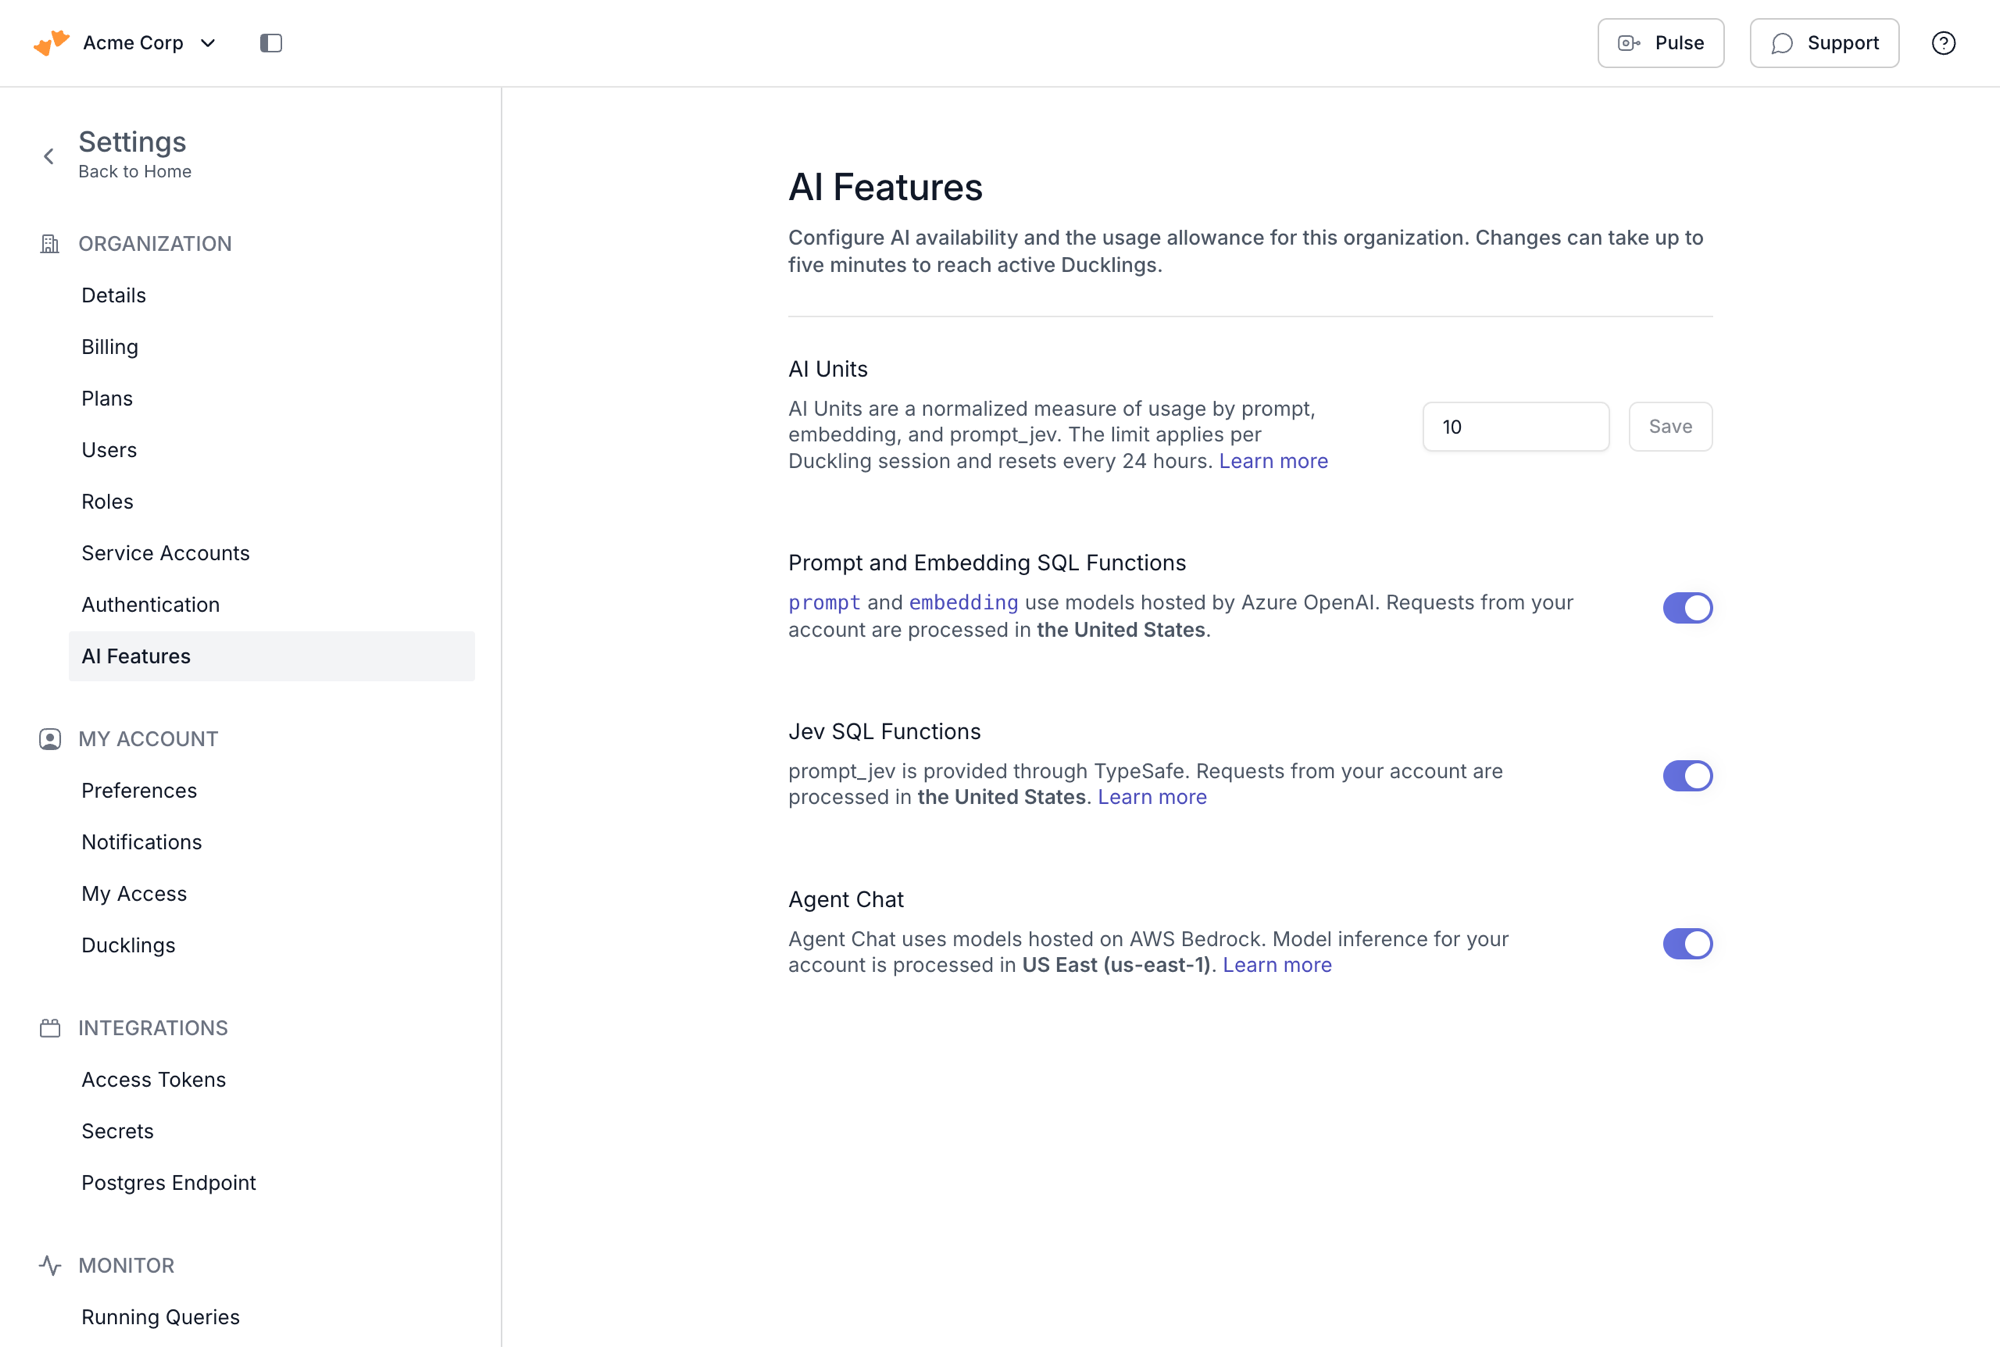
For Lite and Business plans, the default AI session cap is 10 AI Units per Duckling session. The cap applies to combined usage from Advanced AI functions and helps prevent runaway queries from incurring unexpected costs. In long-running Duckling sessions, AI Unit usage resets after 24 hours. Admins can raise the cap for larger batch workloads on the AI Features page in Settings.
Embedding models
embedding is billed on input tokens only. Generating the embedding vector doesn't add an output-token charge.
| Model maker | Model Name | model value | Input Tokens per AI Unit1 |
|---|---|---|---|
| OpenAI | text-embedding-3-small | 'text-embedding-3-small' | 40,000,000 |
| OpenAI | text-embedding-3-large | 'text-embedding-3-large' | 6,153,846 |
Generative prompt models
prompt bills input and output tokens separately at model-specific rates.
| Model maker | Model Name | model value | Input Tokens per AI Unit1 | Cached Input Tokens per AI Unit1 | Cache-write Input Tokens per AI Unit1 | Output Tokens per AI Unit1 |
|---|---|---|---|---|---|---|
| OpenAI | GPT-6 Luna | 'gpt-6-luna' | 8,000,000 | 80,000,000 | 6,400,000 | 1,600,000 |
| OpenAI | GPT-6 Luna (>272K input) | 'gpt-6-luna' | 4,000,000 | 40,000,000 | 3,200,000 | 1,066,667 |
| OpenAI | GPT-5 | 'gpt-5' | 640,000 | 6,400,000 | 640,000 | 80,000 |
| OpenAI | GPT-5-mini | 'gpt-5-mini' | 3,200,000 | 32,000,000 | 3,200,000 | 400,000 |
| OpenAI | GPT-5-nano | 'gpt-5-nano' | 16,000,000 | 160,000,000 | 16,000,000 | 2,000,000 |
| OpenAI | GPT-4.1 | 'gpt-4.1' | 400,000 | 1,600,000 | 400,000 | 100,000 |
| OpenAI | GPT-4.1-mini | 'gpt-4.1-mini' | 2,000,000 | 8,000,000 | 2,000,000 | 500,000 |
| OpenAI | GPT-4.1-nano | 'gpt-4.1-nano' | 8,000,000 | 32,000,000 | 8,000,000 | 2,000,000 |
| OpenAI | GPT-4o | 'gpt-4o' | 320,000 | 640,000 | 320,000 | 80,000 |
| OpenAI | GPT-4o-mini | 'gpt-4o-mini' | 5,333,333 | 10,666,667 | 5,333,333 | 1,333,333 |
See Calculate token charges for cache usage and the long-context threshold.
'gpt-4o-mini' is the default model for prompt, and 'text-embedding-3-small' is the default for embedding.
Only input and output tokens are billed for AI usage. There is no per-row or per-call charge. The prompt, embedding, and prompt_jev references use these rates to estimate rows per AI Unit for example workloads.
Classification models
| Model maker | Model Name | Function | Input Tokens per AI Unit1 | Output Tokens per AI Unit |
|---|---|---|---|---|
| TypeSafe | Jev | prompt_jev | 19,047,619 | Free |
Jev powers prompt_jev. Only input tokens are metered, and output tokens are free. Input includes the text and question content sent to the model, so source-text length alone doesn't determine the charge. prompt_jev is available in all regions, and is off by default in eu-central-1 and eu-west-1. Requests from every cloud region are processed by TypeSafe's servers in the United States.
Footnotes
Calculate token charges
For generative prompts, add the token charges using the rates above:
AI Units =
    uncached input tokens / input tokens per AI Unit
    + cached input tokens / cached input tokens per AI Unit
    + cache-write input tokens / cache-write input tokens per AI Unit
    + output tokens / output tokens per AI Unit
Cached input reuses stored prompt tokens, while cache-write input stores tokens for reuse. Apply these rates only when Azure OpenAI reports the corresponding counts. Uncached input is total input minus both counts.
When a GPT-6 Luna request has more than 272,000 total input tokens, including cache usage, all its input and output tokens use the long-context rates. For reasoning models, output-token counts include reasoning tokens.
For example, 250 uncached input tokens and 62.5 output tokens per row with gpt-4o-mini consume 250 / 5,333,333 + 62.5 / 1,333,333 ≈ 0.00009375 AI Units per row. That is about 10,700 rows per AI Unit, or 0.9375 AI Units for 10,000 rows. The fractional output-token count represents an average across rows.
For embeddings and Jev, use only the input term. Character counts don't convert to the same number of tokens for every model or language, so use token usage when estimating costs.
SQL assistant functions
These features, including FixIt and Text-to-SQL, help you write, understand, and correct SQL queries.
SQL Assistant functions are available on Lite and Business plans. FixIt is free, while the other assistant functions have the per-call charge below.
| SQL Assistant function | Price | Unit |
|---|---|---|
| FixIt | Free | Per call |
| SQL Assistant (Text-to-SQL, Explain SQL, and other assistant functions) | 1 AI Unit | 160 calls |
Incentive programs:
Free trial
New users who sign up for MotherDuck and create an organization automatically get access to a 7-day Free Trial without entering a credit card. Learn how to manage your plan after the trial has ended.
At any point during your Free Trial, you may choose to set up billing and select a plan. At the end of your trial, you can continue with the Lite plan (no credit card required) or upgrade to Business for additional features. Learn more about managing your bill.