Is Your Postgres Slow at Answering Analytics Questions?

2026/06/09Featuring:

TL;DR: Postgres is a transactional database, not an analytical one. When dashboards and customer-facing analytics start timing out, the fix isn't a bigger instance — it's routing analytical reads to a columnar engine. Mehdi Ouazza shows how to keep Postgres as your system of record while MotherDuck handles the heavy queries.

When Postgres hits its analytical ceiling

Postgres is a transactional database. When you start running large aggregations and concurrent dashboard reads against row-based storage, it shows. Pages take ten seconds to load, API gateways time out, read replicas don't actually help. These aren't tuning problems. You've outgrown Postgres for analytical work.

The usual patches stop scaling

Read replicas, materialized views, bigger instances — they all buy time but none fix the underlying mismatch. Replicas still do row-based scans. Materialized views go stale or get expensive to refresh. Scaling up costs more every quarter and you're still running OLAP queries on an OLTP engine.

Keep Postgres, add a columnar engine

Postgres stays as the system of record. Analytical reads go to an engine built for them. Columnar storage reads only the columns a query touches, so aggregations over millions of rows come back in milliseconds instead of seconds. MotherDuck runs DuckDB in the cloud — you get that speed without standing up a full data warehouse.

Pick the right ingest pattern

Mehdi walks through four ways to move Postgres data into MotherDuck: batch loads, change data capture (CDC), in-place reads, and the Postgres wire protocol. Each trades off freshness against complexity differently. The session ends with a live demo connecting a Postgres database to MotherDuck, running analytical queries, and feeding results into a dashboard. You can try it yourself in a few minutes.
FAQS

Postgres stores data in rows, which works well for the kind of read-a-record, write-a-record work most applications do. But when you run a query that scans millions of rows to compute a sum or a group-by, it reads every column in every row even if you only care about two of them. That's a lot of wasted I/O, and it's happening on the same database your application is trying to use for normal operations.

This is the OLTP-vs-OLAP mismatch. Postgres is built for the former. Analytical queries belong in the latter.

Read replicas and materialized views help for a while, but they don't fix the real problem. Read replicas still run the same row-based scans. Materialized views go stale, and refreshing them gets slower as your data grows. Scaling the instance up just means a bigger bill every quarter. If your analytics workload keeps growing, you're better off routing those queries to a columnar engine than trying to patch Postgres into something it isn't.

Keep Postgres as your system of record and route analytical queries to a columnar engine like MotherDuck. You can load data by batch, change data capture (CDC), in-place reads, or the Postgres wire protocol. Pick whichever matches how fresh the data actually needs to be. This saves you from standing up a full data warehouse when you don't need one. See the getting started guide to connect your first database.

OLTP (online transaction processing) handles many small reads and writes — inserting an order, updating a user record. It's what Postgres was built for. OLAP (online analytical processing) sits at the other end: big scans across millions of rows, like computing revenue by region over a full year. There's more on this in our OLAP guide.

Start with the queries that hurt most: big aggregations, dashboard rollups, and the ad-hoc exploratory stuff where someone scans an entire table. Those are the ones hogging resources and making your application feel sluggish. Keep transactional reads and writes on Postgres, where they belong.

Related Videos

"Jev for Analytics: 5 Use Cases on Real Data" video thumbnail

43:57

2026-10-08

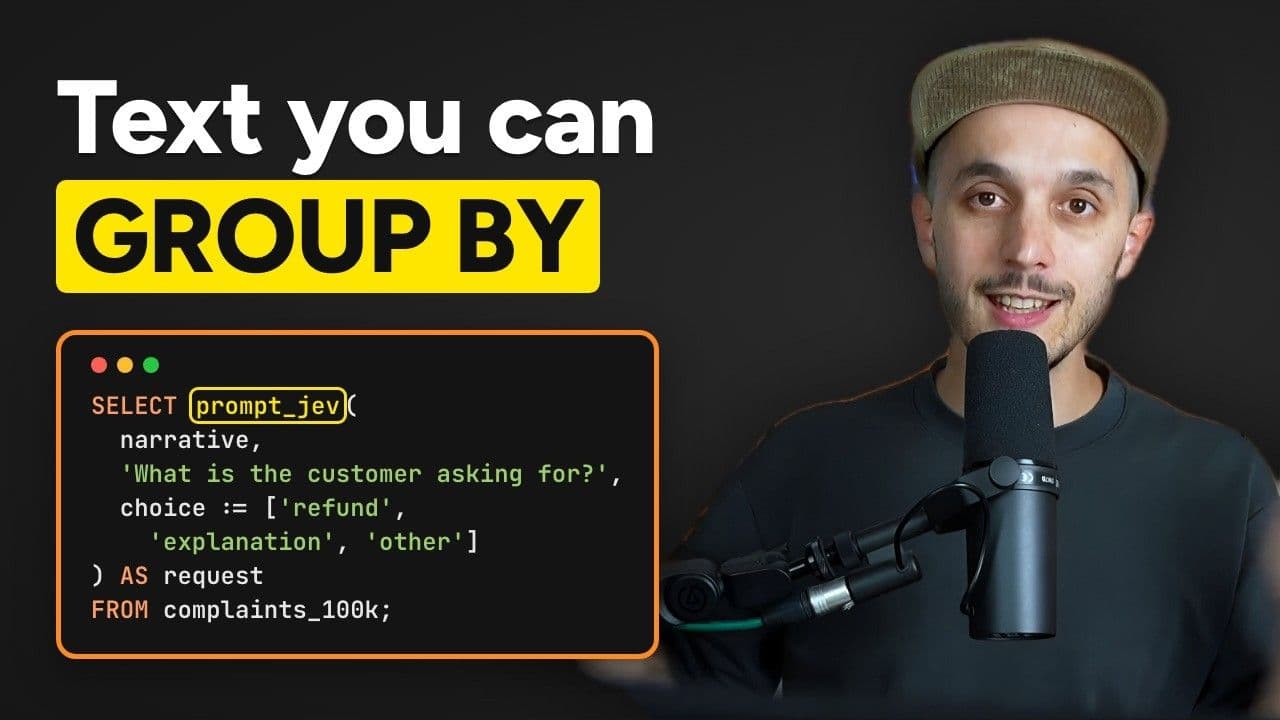
Jev for Analytics: 5 Use Cases

Mehdi Ouazza uses MotherDuck's prompt_jev() to turn text columns into columns you can GROUP BY. He classifies 100,000 consumer complaints, then walks through five use cases on real data: AI agent logs, Hacker News sentiment, sales calls, and two kinds of job-ad analysis.

Stream

MotherDuck Features

AI ML and LLMs

"Virtual Workshop: Build a Data Agent in 60 Minutes" video thumbnail

51:58

2026-10-01

Build a Data Agent in 60 Minutes

Jacob Matson walks through a working data chat agent he built: MCP tools, an agentic loop, a tuned system prompt, hard-coded read-only guardrails, and telemetry. He demos it live against a real dataset, walks through the actual codebase, then shows the same backend re-platformed into a Slack bot.

Stream

MotherDuck Features

AI ML and LLMs

Data Pipelines

"We Classified 100,000 Rows in 40 Seconds: Introducing prompt_jev()" video thumbnail

49:02

2026-09-29

prompt_jev(): SQL-Native Text Classification

MotherDuck's new prompt_jev() function runs text classification directly from SQL using Jev, a decision-focused model from typesafe.ai. In a live demo, Jacob Matson, Dumky de Wilde, and Hamilton Ulmer showed it filtering, disambiguating, and re-ranking real data without leaving SQL. The number they kept coming back to: 100,000 rows classified at 89% accuracy in 40 seconds, compared to 32 minutes and $37.58 for a comparable LLM call.

Stream

MotherDuck Features

AI ML and LLMs

Data Pipelines