Less than three weeks before Data Outpost. Get your ticket before they sell out.Join AI and Data builders Nov 4-5 in SF

Agentic Data Engineering: Building Pipelines End-to-End with AI

May 19, 2026Featuring: ,

TL;DR

Hugo Lu (Orchestra) and Jacob Matson (MotherDuck) demo an AI agent that builds a complete data pipeline from a single natural language prompt — ingesting data from Linear, landing it in a MotherDuck staging database, promoting it to production via snapshots, and visualizing results in a Dive — all orchestrated through Orchestra and wired together with MCP.

Why AI changes how we build pipelines

AI models are good at writing SQL and structuring messy data, but they query differently than humans. Agents fire off lots of small, bursty queries to explore a database before they do anything useful. MotherDuck's DuckDB-based architecture handles this well — it's fast, runs queries in parallel via vectorization, and costs roughly 10x less than Snowflake or Redshift for comparable workloads.

The demo: one skill, one agent, one pipeline

Hugo built a single Claude Code skill that tells the agent how to scaffold an end-to-end pipeline. When triggered, the agent:

  1. Generates a Python ingestion script using DLT (with a connector it created on the fly for Linear)
  2. Writes an Orchestra pipeline YAML file to orchestrate the run
  3. Pushes everything to a feature branch
  4. Triggers the pipeline in Orchestra

The whole setup needs three sets of credentials (Linear, MotherDuck, Orchestra) and the MotherDuck MCP server for database operations. No custom skills needed for the warehouse layer.

Staging, snapshots, and safe promotion

Rather than writing directly to production, the agent lands data in a staging database. MotherDuck snapshots create an immutable, zero-copy checkpoint of that database. If everything looks right, the snapshot gets promoted to production. If something breaks, you roll back. This keeps unattended agent workflows reversible and safe.

Dives: BI as code from your pipeline

At the end of the pipeline, the agent also updates a MotherDuck Dive — a React-based visualization that lives in source control. The Dive shows when data was last refreshed and links back to the Orchestra run for full lineage. No dashboard tool to learn; the AI writes the TSX.

Q&A highlights

  • Storage cost of snapshots: MotherDuck keeps 7 days of snapshots by default. If you build incrementally, the overhead is minimal. Transient databases reduce retention further.
  • Token efficiency: The demo used roughly 10,000 tokens. Both MotherDuck and Orchestra keep MCP tool descriptions concise to avoid blowing up context windows.
  • Semantic/modeling layers: You can extend the Orchestra pipeline YAML to include dbt modeling steps between ingestion and snapshot promotion.
FAQS

MotherDuck is a cloud data warehouse built on DuckDB. It runs SQL queries using vectorized, parallel execution on your CPU, so it's fast and cheap. In this webinar, Jacob Matson compares MotherDuck's cost and speed against legacy warehouses and walks through why the architecture works well for agents that hit the database constantly.

Orchestra is a serverless orchestration engine. You define pipelines in YAML, and it handles monitoring, metadata, alerting, and lineage. In the demo, Hugo has Claude Code generate the Python ingestion code and the Orchestra pipeline YAML, then kick off the pipeline — all from a single natural language prompt.

MotherDuck snapshots are immutable, point-in-time copies of a database. They use zero-copy cloning, so promoting data from staging to production is fast and costs almost nothing in extra storage. They also work as an undo button — if an agent breaks something, you roll back to the snapshot instead of re-running the whole pipeline. MotherDuck keeps 7 days of snapshots by default, and for incremental workloads the extra storage is negligible.

A MotherDuck Dive is a set of TSX (React) files that render interactive visualizations from your warehouse data. Dives live in source control, so they're versioned and reproducible. In this demo, the AI agent generates and updates a Dive at the end of the pipeline — no manual dashboard building needed.

The demo used a single Claude Code skill — a markdown file with step-by-step instructions telling the agent how to scaffold the pipeline. Hugo's skill was verbose (AI-generated), but you could write the same thing in about 20 lines. The skill references the MotherDuck MCP server for database operations, so no custom MotherDuck-specific skills were needed.

Related Videos

"Jev for Analytics: 5 Use Cases on Real Data" video thumbnail

43:57

Oct 8, 2026

Jev for Analytics: 5 Use Cases

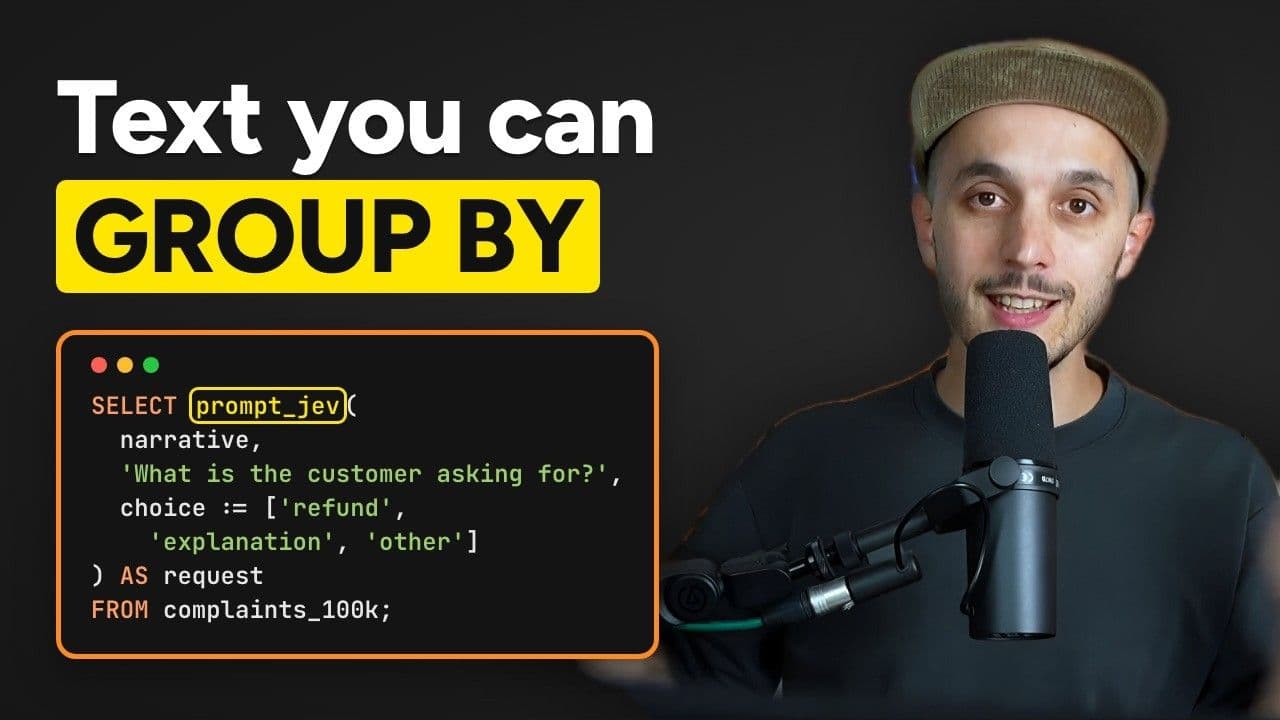
Mehdi Ouazza uses MotherDuck's prompt_jev() to turn text columns into columns you can GROUP BY. He classifies 100,000 consumer complaints, then walks through five use cases on real data: AI agent logs, Hacker News sentiment, sales calls, and two kinds of job-ad analysis.

Stream

MotherDuck Features

AI ML and LLMs

"Virtual Workshop: Build a Data Agent in 60 Minutes" video thumbnail

51:58

Oct 1, 2026

Build a Data Agent in 60 Minutes

Jacob Matson walks through a working data chat agent he built: MCP tools, an agentic loop, a tuned system prompt, hard-coded read-only guardrails, and telemetry. He demos it live against a real dataset, walks through the actual codebase, then shows the same backend re-platformed into a Slack bot.

Stream

MotherDuck Features

AI ML and LLMs

Data Pipelines

"We Classified 100,000 Rows in 40 Seconds: Introducing prompt_jev()" video thumbnail

49:02

Sep 29, 2026

prompt_jev(): SQL-Native Text Classification

MotherDuck's new prompt_jev() function runs text classification directly from SQL using Jev, a decision-focused model from typesafe.ai. In a live demo, Jacob Matson, Dumky de Wilde, and Hamilton Ulmer showed it filtering, disambiguating, and re-ranking real data without leaving SQL. The number they kept coming back to: 100,000 rows classified at 89% accuracy in 40 seconds, compared to 32 minutes and $37.58 for a comparable LLM call.

Stream

MotherDuck Features

AI ML and LLMs

Data Pipelines