Text-to-SQL, Data Modeling for LLMs, MCP, and Dives with Jacob Matson

2026/03/12Featuring: ,

TL;DR: Jacob Matson comes on the Super Data Brothers show to talk about his text-to-SQL research, why your data model matters more than which LLM you pick, a demo of the MotherDuck MCP server, and Dives, MotherDuck's new interactive data visualization feature.

Text-to-SQL accuracy is a data modeling problem, not an LLM problem

Jacob walks through his research on the Bird Bench text-to-SQL benchmark. The big finding: give an LLM a clean, well-named data model and accuracy goes way up. On simple schemas, models like Claude can hit 90%+ accuracy on text-to-SQL benchmarks. A lot of the remaining errors in popular benchmarks actually come from annotation mistakes in the benchmarks themselves. Jacob found roughly a 20-30% error rate in the Bird Bench mini dev set.

The practical takeaway: if your column and table names make sense to a human, they'll make sense to an LLM. If they confuse a person, they'll confuse AI too. Jacob suggests thinking about an "AI-ready" data layer where you flatten joins and use descriptive names, even if it offends your inner star-schema purist.

Context matters more than you think

When adding context to help LLMs write SQL, Jacob says to focus on things the model can't figure out on its own. Definitions of fiscal years, business-specific metric logic, domain terminology - that's the high-value stuff. Statistical metadata like min/max values and enum lists help too. But restating what the LLM can already infer from column names just wastes context window space. He compares it to a Sudoku puzzle: each confirmed golden question-answer pair constrains the space of possible wrong answers.

The MotherDuck MCP server changes how you work with data

Jacob and the host both use the MotherDuck MCP server daily. The workflow is straightforward: ask a question in natural language, get SQL back, review it, run it. Internally at MotherDuck, a pattern has emerged where people use traditional BI dashboards as a source of truth for known metrics, then use the MCP to slice and explore beyond what those dashboards cover. Non-technical team members can self-serve their own data questions for the first time.

Dives turn SQL results into shareable interactive apps

MotherDuck Dives are interactive data visualizations built from SQL queries. Jacob explains that Dives started as a way to share analysis with non-technical stakeholders but have turned into lightweight data apps. You can create Dives through the MotherDuck MCP server, which means you can go from a natural language question to a shareable interactive visualization without opening a separate BI tool. The host runs the Super Data Brothers business backend on them.

What's ahead for MotherDuck

Jacob is honest about the uncertainty: nobody knows whether AI progress keeps compounding or levels off. Near-term, MotherDuck's roadmap includes enterprise features like finer-grained role-based access control, row-level security, and higher-scale partition handling. On the AI side, the team is exploring whether Claude and similar tools become the primary way people interact with data apps, which is part of why Dives were built to work through the MCP in the first place.
FAQS

It depends on the data model more than the LLM itself. On clean schemas with descriptive column and table names, models like Claude can hit 90%+ accuracy on text-to-SQL benchmarks. Jacob Matson's research on Bird Bench found that many supposed LLM "errors" were actually wrong annotations in the benchmark - something like 20-30% of questions had incorrect gold answers. The takeaway: if your data model is well-named and well-organized, current LLMs are already good enough for most analytical SQL work.

The MotherDuck MCP server lets you query your MotherDuck data warehouse from AI tools like Claude, Cursor, or Claude Code using natural language. You ask a question, the LLM writes SQL, and you review and run it against your actual data. At MotherDuck, teams use it alongside traditional BI dashboards. Dashboards are the source of truth for standard metrics, and the MCP server handles ad hoc exploration and slicing that dashboards don't cover.

Column and table names matter more than anything else. If a human can't figure out what a column means from its name, an LLM won't either. Jacob recommends building a flattened "AI-ready" data layer - a single wide table or simplified joins - to cut down on join errors. When adding context, focus on what the LLM can't figure out on its own: fiscal year definitions, business-specific metric calculations, and domain terminology. Don't bother restating what's already obvious from the schema. See the DuckDB tutorial for beginners for more on structuring your data.

Dives are interactive data visualizations you build from SQL queries in MotherDuck. They started as a way to share analysis with non-technical teammates but have turned into lightweight data apps. You can create Dives through the MotherDuck MCP server, so you can go from a natural language question to a shareable visualization without opening a separate BI tool.

Not entirely, at least not yet. The pattern Jacob describes at MotherDuck is hybrid: traditional BI dashboards stay as the source of truth for known, recurring metrics, while LLM-powered tools like the MotherDuck MCP server handle ad hoc questions and one-off exploration. The bigger shift is that people who couldn't self-serve data questions before - because they didn't know SQL - can now get answers through natural language. Dashboards and AI querying work better together than either does alone.

Related Videos

"Jev for Analytics: 5 Use Cases on Real Data" video thumbnail

43:57

2026-10-08

Jev for Analytics: 5 Use Cases

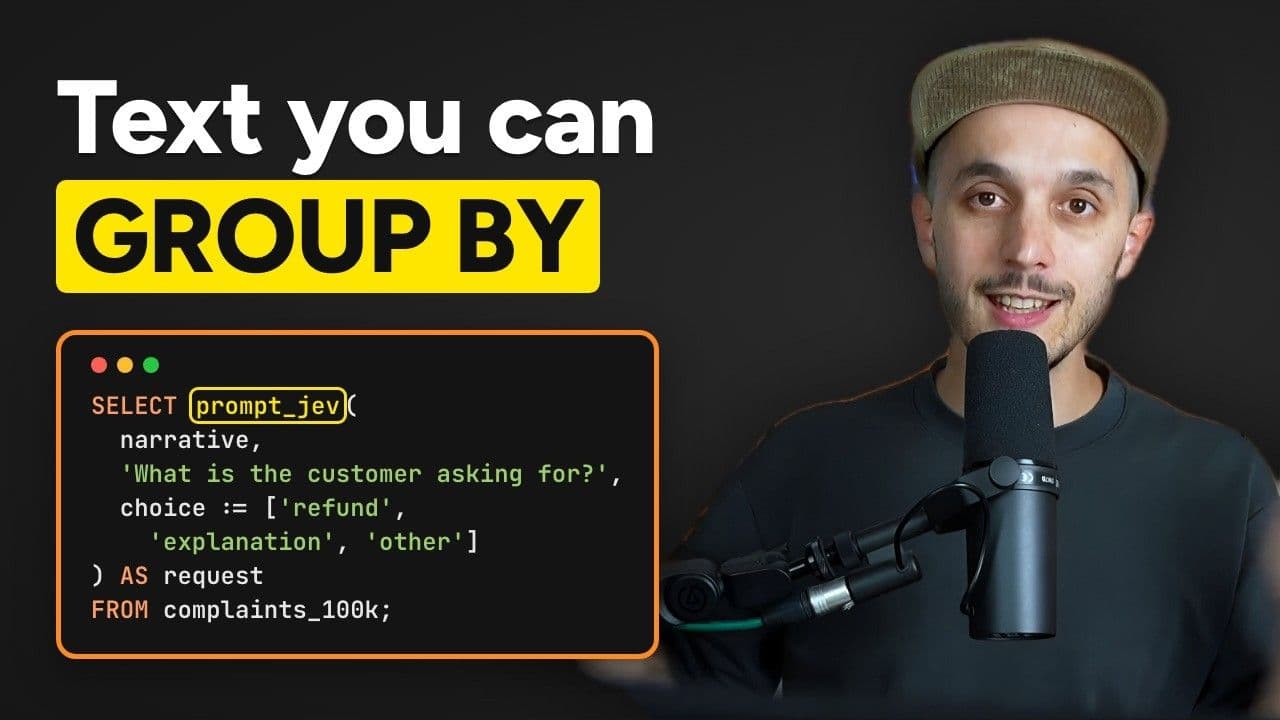
Mehdi Ouazza uses MotherDuck's prompt_jev() to turn text columns into columns you can GROUP BY. He classifies 100,000 consumer complaints, then walks through five use cases on real data: AI agent logs, Hacker News sentiment, sales calls, and two kinds of job-ad analysis.

Stream

MotherDuck Features

AI ML and LLMs

"Virtual Workshop: Build a Data Agent in 60 Minutes" video thumbnail

51:58

2026-10-01

Build a Data Agent in 60 Minutes

Jacob Matson walks through a working data chat agent he built: MCP tools, an agentic loop, a tuned system prompt, hard-coded read-only guardrails, and telemetry. He demos it live against a real dataset, walks through the actual codebase, then shows the same backend re-platformed into a Slack bot.

Stream

MotherDuck Features

AI ML and LLMs

Data Pipelines

"We Classified 100,000 Rows in 40 Seconds: Introducing prompt_jev()" video thumbnail

49:02

2026-09-29

prompt_jev(): SQL-Native Text Classification

MotherDuck's new prompt_jev() function runs text classification directly from SQL using Jev, a decision-focused model from typesafe.ai. In a live demo, Jacob Matson, Dumky de Wilde, and Hamilton Ulmer showed it filtering, disambiguating, and re-ranking real data without leaving SQL. The number they kept coming back to: 100,000 rows classified at 89% accuracy in 40 seconds, compared to 32 minutes and $37.58 for a comparable LLM call.

Stream

MotherDuck Features

AI ML and LLMs

Data Pipelines